
How GPT-6 Astra Fixed Qwen3.5-0.8B by Editing 0.016% of Its Weights
 Hassann
GPT-6 Astra raised Qwen3.5-0.8B’s MATH-500 score from 7.9% to 48.1% without any training. It read the...
GPT-6 Astra raised Qwen3.5-0.8B’s MATH-500 score from 7.9% to 48.1% without any training. It read the model’s weights, found one direction that made the model loop in its thinking, and subtracted it from two MLP layers. That edit touched 131,072 weights, 0.016% of the model. The numbers come from a November 2 post by four MIT CSAIL researchers, and the edited model is public, so you can check the claim yourself.
Below: what weight-space programming is, what Astra changed, where the method stops working, and how to have your coding agent compare both models with Apidog CLI.
What is weight-space programming?
Weight-space programming is a general-purpose LLM reading and writing a neural network’s weights directly, guided by a plain-language goal, with no gradient descent and no training loop. The model reasons about what each part of the network computes, then changes the numbers by hand, the way a programmer edits source code.
The term comes from Sparks of Weight-Space Programming by Rikiya Takehi, Jayden Teoh, Alex Zhang and Omar Khattab, published November 2, 2026. The authors call every result “very early”, and several come from one or a few runs. For background on the model doing the editing, see the GPT-6 Astra hands-on review.
How GPT-6 Astra fixed Qwen3.5-0.8B
The headline result is Experiment 8. The researchers asked GPT-6 Astra to make Qwen3.5-0.8B better at math by editing its weights. Here’s what happened, step by step:
- The setup. Astra got a Python session (like a notebook) with the model’s weights loaded, no GPU, and 7,469 GSM8K plus 7,275 MATH practice problems from the training sets. It never saw the test sets.
- The budget. Instead of training, Astra could spend 10, 25 or 50 forward passes. One forward pass let the model answer up to 512 problems or read up to 1,024 texts.
- The diagnosis. Astra saw that the base model loops: 85 of its first 96 practice answers ran to the 32,768-token limit without reaching an answer. The authors note that Qwen’s own model card warns this model is prone to thinking loops.
- The trace. Astra traced the looping to one direction written by the MLPs of layers 15 and 19.
-
The edit. It subtracted that direction from 64 output columns of
down_projin each of the two layers. That’s 131,072 weights out of 0.8 billion.

According to the Hugging Face model card, only those two down_proj tensors differ from the base Qwen/Qwen3.5-0.8B checkpoint, and each rebuilt tensor is sha256-verified against the one the authors evaluated. The edited model ships under Apache 2.0.
Results: base vs edited Qwen3.5-0.8B
Every figure here is from the authors’ post (thinking on, up to 32,768 tokens, several samples per problem). “Hit token limit” is the share of MATH-500 answers that ran out of tokens.
| Qwen3.5-0.8B | MATH-500 | GSM8K | IFEval | Hit token limit |
|---|---|---|---|---|
| Base | 7.9% | 13.8% | 21.0% | 93.0% |
| Edited, 10 forward passes | 12.3% | 25.7% | 49.0% | 87.2% |
| Edited, 25 forward passes | 14.1% | 25.1% | 39.9% | 86.4% |
| Edited, 50 forward passes | 48.1% | 67.1% | 62.3% | 33.1% |

- The fix generalized. Looping isn’t specific to math, so IFEval roughly tripled too.
- The budget mattered. At 10 or 25 forward passes the loops barely went away.
- Someone else reproduced it. Ahsen Khaliq at Hugging Face rebuilt the checkpoint from the logs and re-ran the full MATH-500 (500 problems, 4 samples each). The edited model scored 51.0%, with 31.6% of answers hitting the limit. A 25-problem smoke test of the base model gave 5.0%.
The demo Space lets you type a problem and watch both models answer.
What editing weights can’t do
The authors ran a control that matters more than the headline. They tried the same approach on Gemma 3 270M, a model that rarely loops (8.5% of its answers hit the limit, against 93% for Qwen).
| Gemma 3 270M | MATH-500 |
|---|---|
| Base | 6.8% |
| Best edit (25 forward passes) | 7.7% |
Gemma’s errors were ordinary ones, like wrong arithmetic, with no single component to switch off. The authors’ conclusion: editing removed an obstacle that hid an ability, but it couldn’t add an ability the model lacked. Qwen could already work out many answers. It just never finished them.
So this isn’t “training is over”. It’s a frontier model finding and removing one failure that lives in one place.
The rest of the weight-space programming paper
Experiment 8 is one of eight. The others use much smaller networks:
- Reading weights. From raw weights alone, Astra named the game for 4 of 4 PPO-trained game policies and the training language for 3 of 3 small character-level language models.
- Fixing a policy. A Kinetix car policy that failed 256 of 256 episodes succeeded in 1,024 of 1,024 after Astra edited 3.5% of its weights in one reply.
- Writing weights from zero. Astra wrote MinAtar Breakout weights that scored 517.4 against 25.3 for PPO trained for 500 million steps. It lost on Seaquest, 53.1 against 88.9.
- Go. It wrote a 1.48-million-weight 9x9 Go network from zeros that, with 50 forward passes, beat an equal-sized PPO network.
- A miss. From weights alone, it couldn’t tell which of two Gemma 3 270M copies was trained to be sycophantic. With access to attention patterns, it picked the sycophant in all three pairs.
The full experiment logs include every prompt, Astra’s reasoning summaries and every piece of code it ran.
Check the Qwen3.5-0.8B thinking loop fix yourself
The cleanest test is to serve both checkpoints behind the same OpenAI-compatible API and send them identical prompts. vLLM does this with one command per model:
vllm serve Qwen/Qwen3.5-0.8B --port 8001 \
  --served-model-name qwen --max-model-len 34816 --gpu-memory-utilization 0.45

vllm serve RikiyaT/Qwen3.5-0.8B-weight-space-programming --port 8002 \
  --served-model-name qwen --max-model-len 34816 --gpu-memory-utilization 0.45
Both servers answer to the name qwen, so one request body works on either port. --max-model-len 34816 matches the model card’s example.
Each request mirrors the authors’ sampling settings and turns thinking on:
{
  "model": "qwen",
  "messages": [{"role": "user", "content": "{{question}}\nPlease reason step by step, and put your final answer within \\boxed{}."}],
  "temperature": 0.6,
  "top_p": 0.95,
  "top_k": 20,
  "presence_penalty": 1.5,
  "max_tokens": 32768,
  "chat_template_kwargs": {"enable_thinking": true}
}
The last \boxed{} value is the answer, and finish_reason says whether the model stopped (stop) or ran out of tokens (length). A length finish is a loop.
If you’d rather not run a GPU, you can test the GPT-6 Astra API the same way, or compare small Qwen models locally with the free Qwen3.5 Ollama setup.
Let your coding agent test both models with Apidog CLI
Grading twenty long generations by hand is a job for your coding agent. Apidog CLI gives the agent environments, test scenarios, data-driven runs and reports, and it runs on your machine, so localhost endpoints work.
Install it and give your agent the skill:
npm install -g apidog-cli@latest
apidog login --with-token <YOUR_TOKEN>
npx -y skills add https://apidog.com   # pick your agent when prompted
Then give Claude Code, Codex, Cursor or OpenCode one [REDACTED PROMPT]
In Apidog project , create two environments: qwen-base at http://localhost:8001
and qwen-edited at http://localhost:8002. Create a test scenario that POSTs to
/v1/chat/completions with the body in request.json, using {{question}} from the
first 10 GSM8K test questions in gsm8k-10.csv. Assert that the last \boxed{} value
equals {{answer}} and that choices[0].finish_reason is not "length". Run it against
both environments and give me a table: correct answers and length finishes per model.
The agent reads the payload schema, validates its JSON and then runs these commands:
bash
apidog environment create qwen-base --project --base-url http://localhost:8001
apidog environment create qwen-edited --project --base-url http://localhost:8002
apidog cli-schema get test-scenario-create
apidog cli-schema validate test-scenario-create --file scenario.json
apidog test-scenario create --project --file scenario.json
apidog run -t --project -e \
-d gsm8k-10.csv --timeout-request 1800000 -r cli,json --out-file qwen-base
apidog run -t --project -e \
-d gsm8k-10.csv --timeout-request 1800000 -r cli,json --out-file qwen-edited
`-d` feeds each CSV row as one iteration. `--timeout-request` is in milliseconds, and a looping answer can take minutes to burn through 32,768 tokens. `-r cli,json` prints a summary and writes a JSON report the agent can diff. The 10 questions come from the [GSM8K test split](https://huggingface.co/datasets/openai/gsm8k).
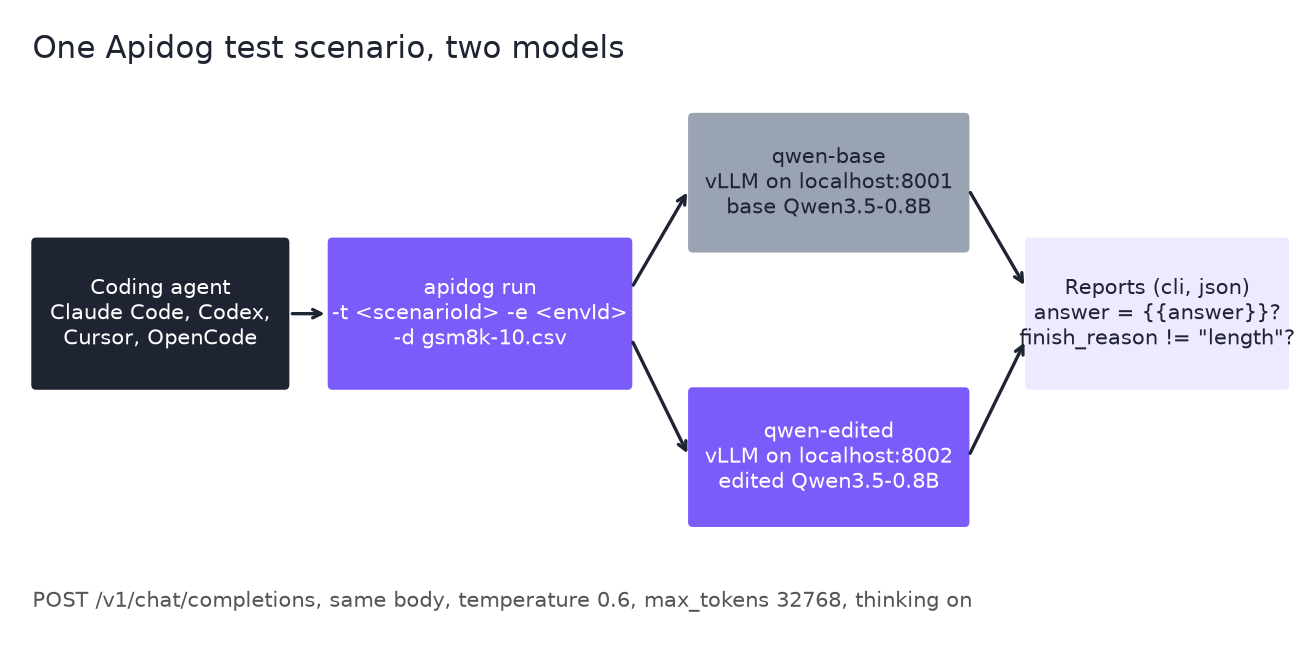
If your run looks like the authors’, most base answers fail the `finish_reason` assertion and most edited answers pass it. Ten questions is a smoke test, not a benchmark, so treat a gap as a signal, not a score. Add `--upload-report` to view the run in the app, and see the [apidog run command reference](http://apidog.com/blog/apidog-run-command-reference?utm_source=dev.to&utm_medium=wanda&utm_content=n8n-post-automation) for every flag.
The same scenario works as a regression test for any model swap; the [Apidog CLI CI/CD guide](http://apidog.com/blog/apidog-cli-ci-cd-pipeline?utm_source=dev.to&utm_medium=wanda&utm_content=n8n-post-automation) shows the `-r junit` setup.
## What this means if you ship small models
- **Measure truncation, not just accuracy.** Qwen’s 7.9% hid a model that mostly never finished. A `finish_reason` check catches that.
- **Look for single-cause failures.** Loops and repetition can live in a narrow part of a network.
- **Remember the control.** If your model is wrong rather than stuck, an edit like this won’t help.
Picking a GPT-6 tier for agent work? See [GPT-6 Luna vs Sol vs Astra](http://apidog.com/blog/gpt-6-luna-vs-sol-vs-astra?utm_source=dev.to&utm_medium=wanda&utm_content=n8n-post-automation).
## FAQ
**Did GPT-6 Astra train Qwen3.5-0.8B?** No. The authors allowed no gradient descent and no training loop. Astra edited weights in a Python session and observed the model only through 10, 25 or 50 forward passes.
**How many weights did the edit change?** 131,072 weights, which the authors put at 0.016% of the model. The changes sit in the `down_proj` matrices of the MLPs in layers 15 and 19, 64 output columns in each.
**Is the edited model available?** Yes, as `RikiyaT/Qwen3.5-0.8B-weight-space-programming` on Hugging Face under Apache 2.0, with hashes of the two changed tensors and an independent re-run (51.0% on MATH-500).
**Why did math scores jump so much?** Because the base model looped. On MATH-500, 93.0% of its answers hit the 32,768-token limit. The edit cut that to 33.1%, so the model finished answers it could already work out. It didn’t learn new math.
**Does weight-space programming work on any model?** Not yet, by the authors’ own account. On Gemma 3 270M, which rarely loops, the best edit moved MATH-500 from 6.8% to 7.7%. The authors call all of their results very early.
**Can I test the edited model without writing code?** Yes. The Hugging Face demo Space runs both models on a problem you type. For a repeatable check, use vLLM plus Apidog CLI as shown above.